

Noindex

Noindex is a directive that tells search engines to keep a page out of their index,…
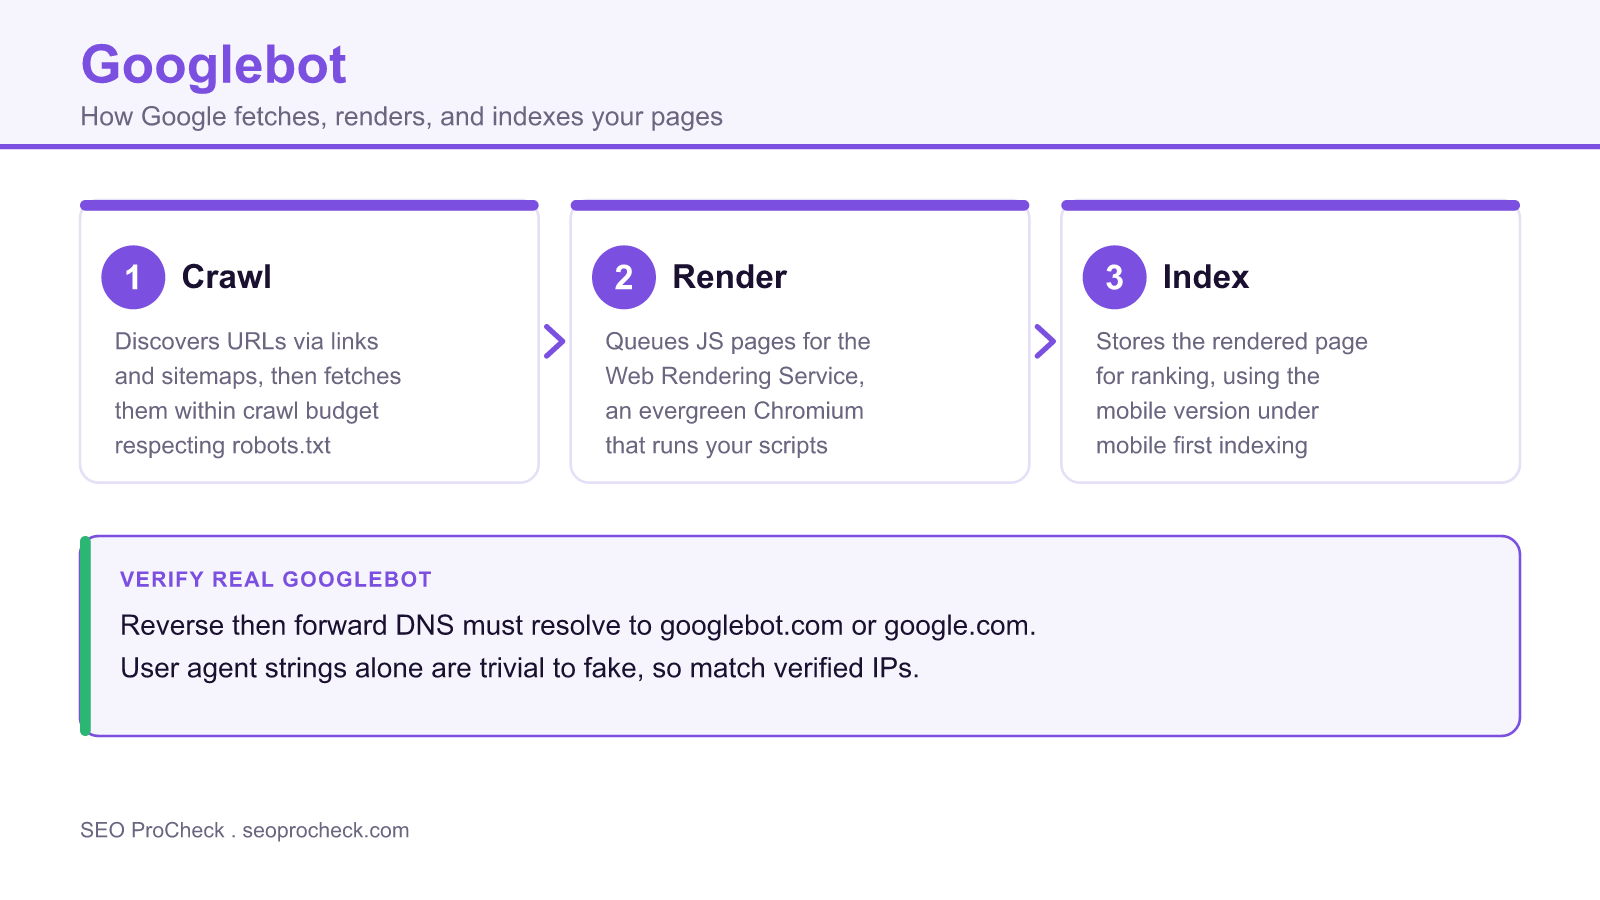
Googlebot is the name of the web crawler Google uses to discover and fetch pages from…

A user-agent is a string a client sends with each request to identify what software is…

llms.txt is a proposed standard for a plain-text file, placed at a site's root, that offers…

AI SEO represents a critical component of modern SEO strategy. As search engines continue to evolve…
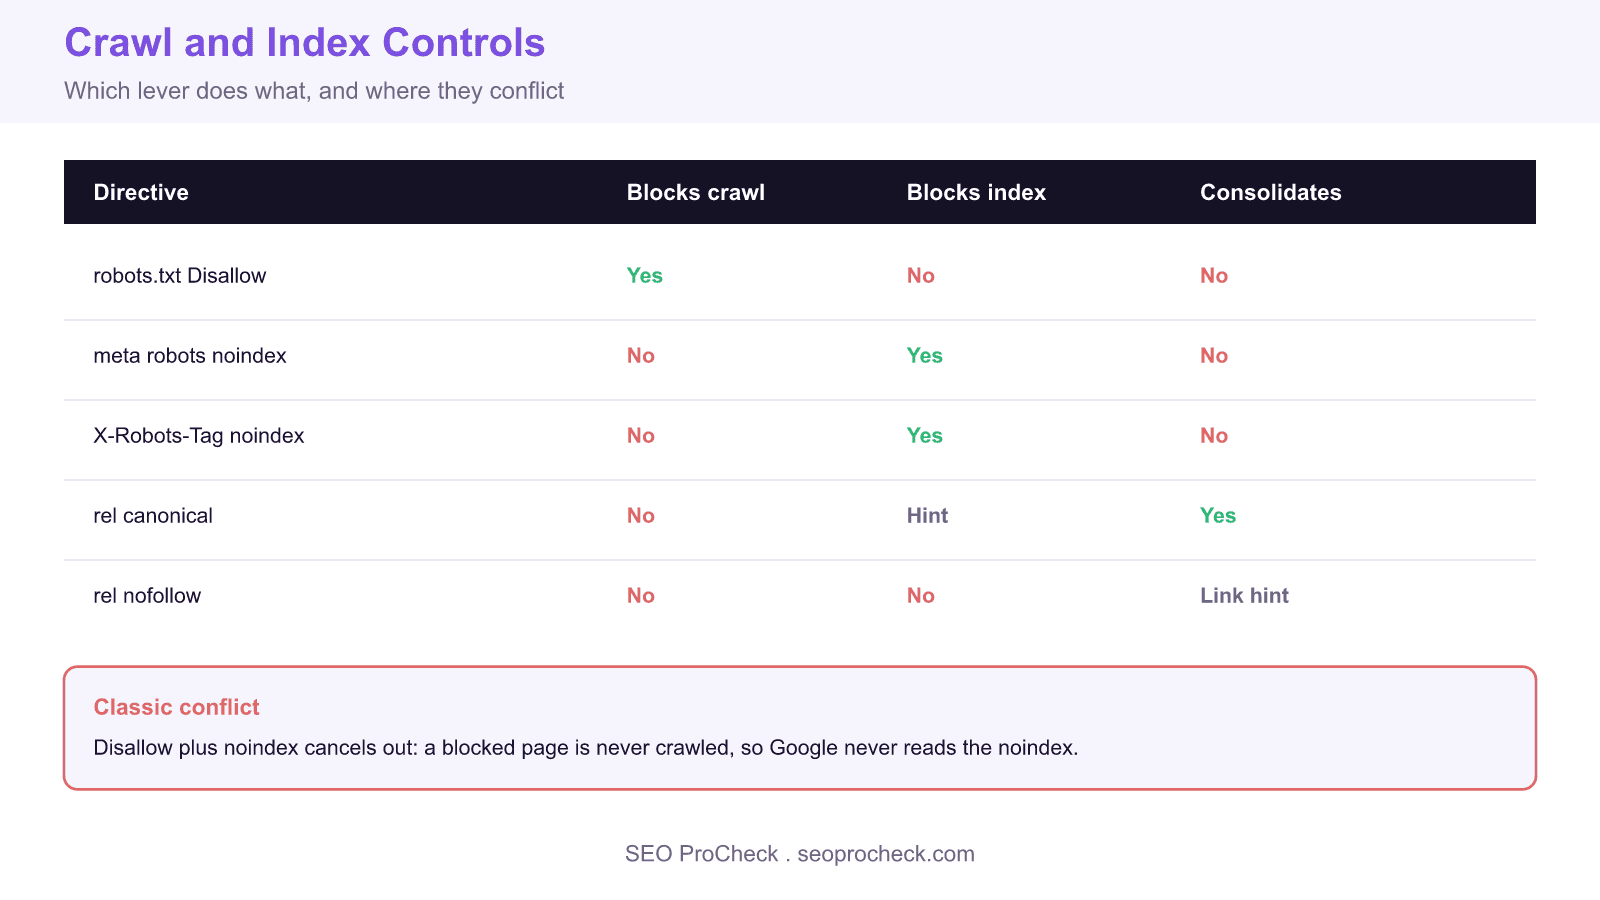
Shaikat Ray walks us through how to improve your page crawling and indexing using noindex, robots.txt…
Get new blog posts by email:
Case studies, research, best practices and free tools for technical SEO, GEO and AI search.
Free tools: SEO & AI search tools · GitHub · browser extensions