Crawling

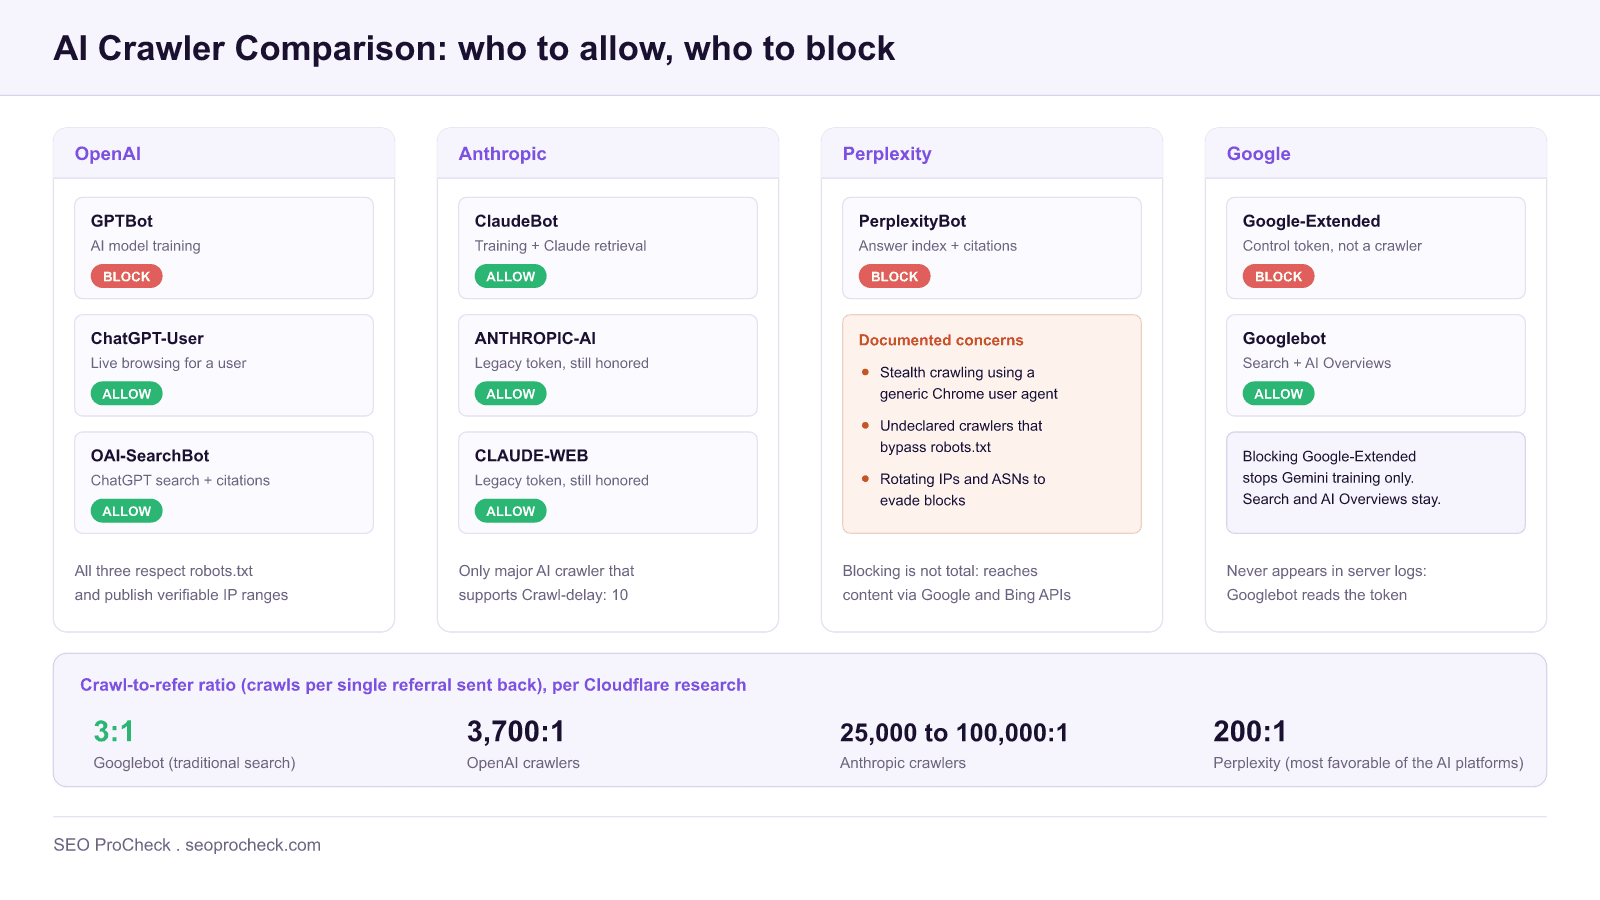
Comparison chart of ai crawlers by operator: openai gptbot blocked while chatgpt-user and oai-searchbot are allowed, anthropic claudebot and its legacy tokens allowed with crawl-delay support, perplexitybot blocked over documented stealth crawling, and google-extended blocked while googlebot stays allowed, plus crawl-to-refer ratios from cloudflare research.

AI Crawler Comparison: GPTBot, ClaudeBot, PerplexityBot Complete Guide

Complete comparison of AI crawlers including GPTBot, ClaudeBot, PerplexityBot, and Google-Extended. Covers robots.txt compliance, Crawl-delay support,…
Learn More
Annotated robots. Txt example showing user-agent, disallow, allow, and sitemap directives next to the difference between crawl control and index control.

Complete Guide to Robots.txt Configuration

Comprehensive guide to robots.txt covering implementation, best practices, troubleshooting, and advanced techniques.
Learn More
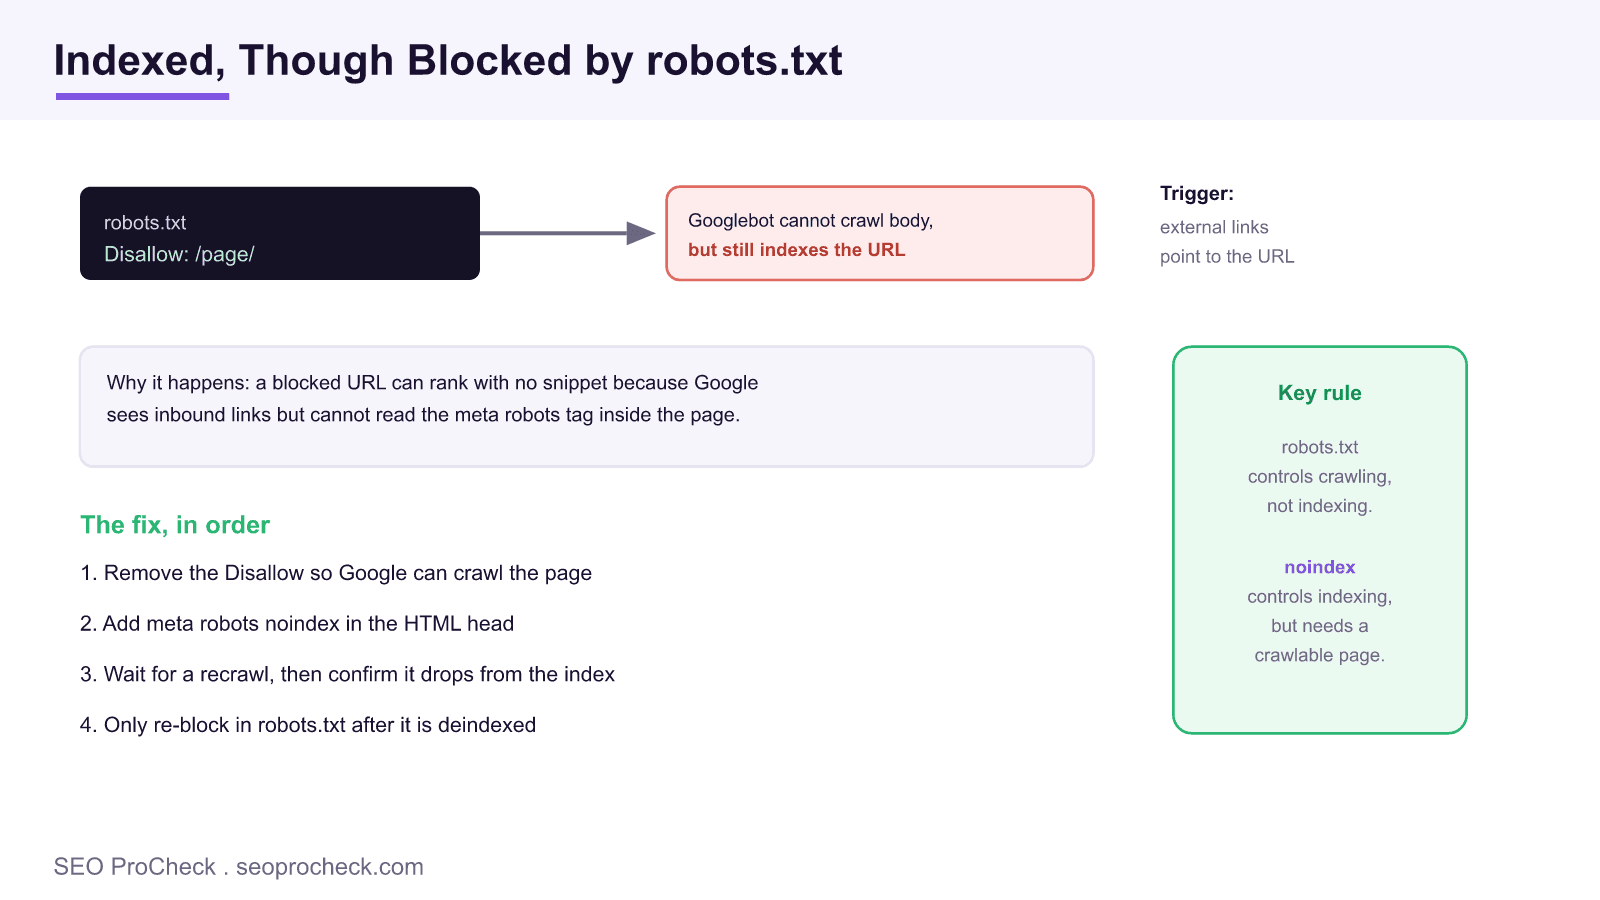
Diagram showing why a url blocked in robots. Txt can still be indexed by google, and the ordered fix of unblocking the url then adding a meta robots noindex tag.

Case study: Fixing “Indexed, though blocked by robots.txt”

A case study by Eoghan Henn on how he fixed Indexed, though blocked by robots.txt file.
Learn More
Claudebot

ClaudeBot

ClaudeBot is the web crawler operated by Anthropic, the company behind the Claude AI assistant. It…
Learn More
Diagram of how search engine crawling discovers and fetches pages before indexing on seoprocheck. Com

Crawling

Crawling is the process by which search engines discover and download pages on the web using…
Learn More
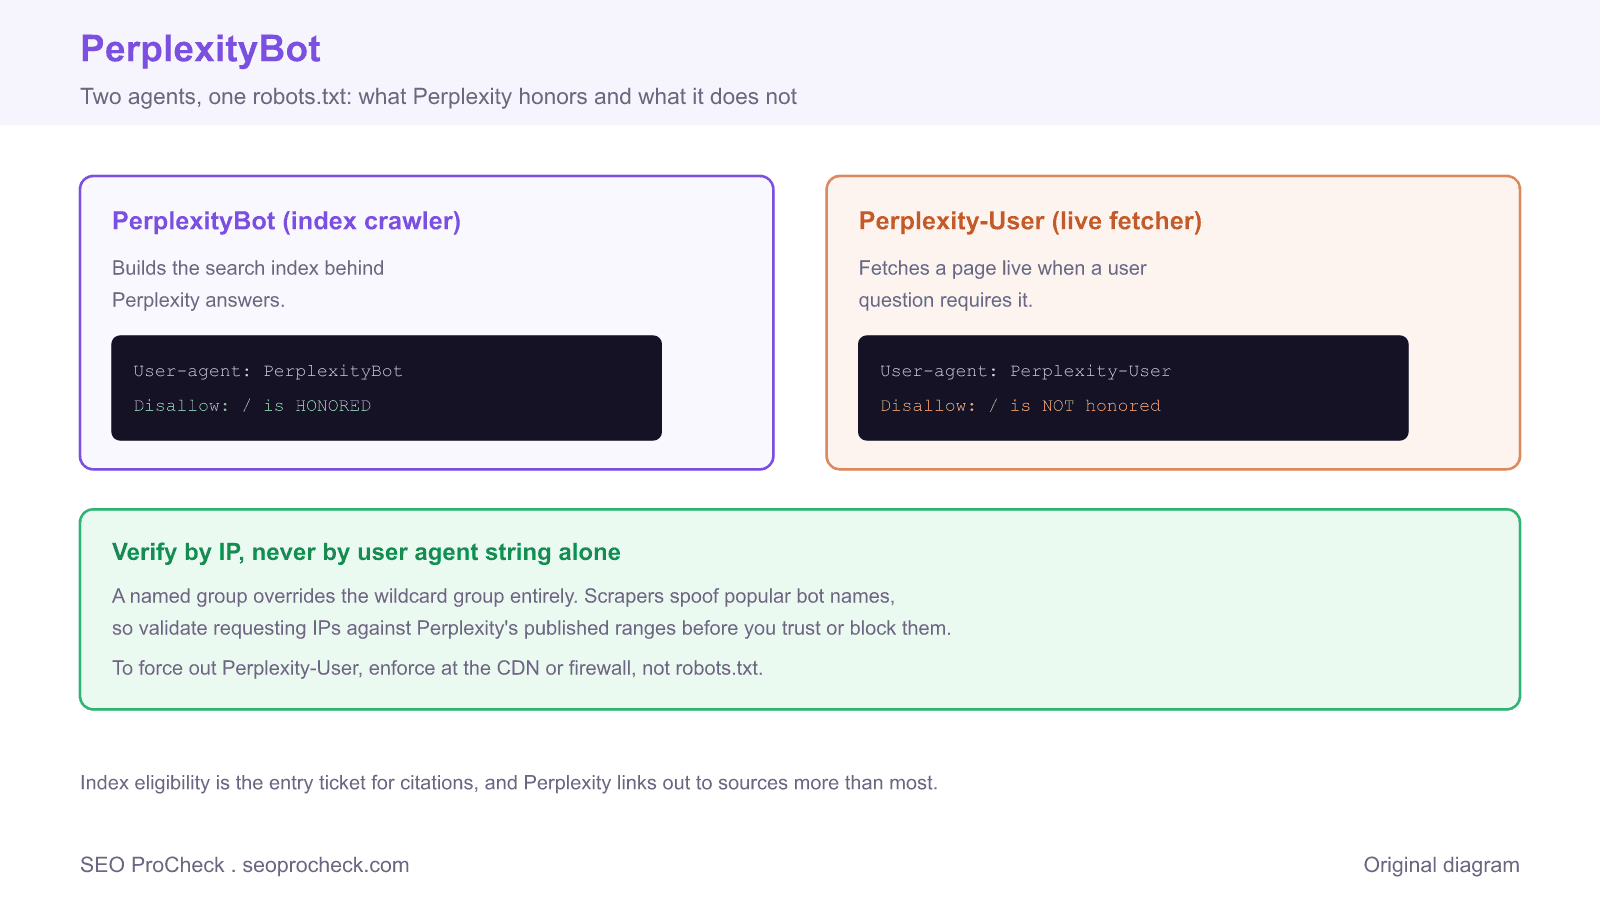
Diagram showing the perplexitybot index crawler honoring a robots. Txt disallow while the perplexity-user live fetcher does not, with a note to verify by ip.

PerplexityBot

PerplexityBot is the web crawler operated by Perplexity, the AI answer engine. It discovers and indexes…
Learn More

Get new blog posts by email: