
Reddit Voice-of-Customer Analysis, Free and Without an API Key
- November 14, 2026
- Python and Automation
TL;DR
reddit-voc is a free command-line tool I built that reads a subreddit and reports which brands own the conversation, what each one is distinctively criticized for, and which questions buyers keep asking. It reads the Arctic Shift public archive, so it needs no Reddit API key, and it is a single Python file with no dependencies.
- The hard part of Reddit analysis is not pulling the data, it is not fooling yourself with it.
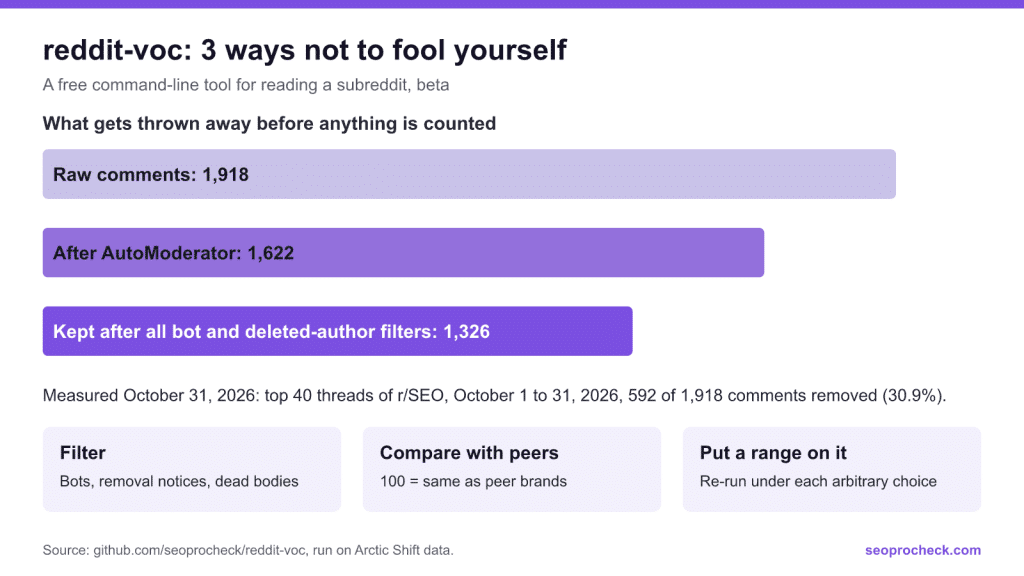
- It filters bots and dead comments before counting. On r/SEO in October 2026, that removed 592 of 1,918 comments.
- It compares complaints against peer brands, not against the whole subreddit.
- It puts a range on the gap between a brand's own community and neutral ground.
- It is beta: the flags and output formats may still change.
I think a lot of what people learn about a product now comes from a forum thread, sometimes quoted back inside an AI answer. In a study by Minuttia and Convex Works of software questions in August 2026, Reddit appeared in 71% of Google Search results and 38% of AI Overviews on alternatives to X questions, and in 24% of ChatGPT answers, while Claude never cited it. That is one category and one snapshot, but it is a good reason to read what a forum says before an engine repeats it.
Reddit is also hard to read well. This article explains why, and walks through the free tool I built to do it.
Why Reddit is voice-of-customer data
Reviews on your own site are curated. Survey answers are shaped by the questions you asked. App store ratings collapse a paragraph of nuance into one star. Reddit is the rare place where people describe a product to each other, with little reason to be diplomatic and a strong reason to be specific, because the audience will call out anything vague.
- It surfaces the question, not just the sentiment. The most replied threads in a category are a ranked list of the decisions your market is trying to make.
- It is comparative. People do not post that they like these headphones. They post X versus Y for a daily commuter who takes a lot of calls, which is exactly what you need to position against competitors.
- It shows the vocabulary. Customers write the way they search, not the way your product team writes.
The catch: reddit.com blocks you, and most scrapers fool you
The first obstacle is access. On October 31, 2026, a plain scripted request for a thread's JSON from my machine answered 403 Forbidden. The official API works, but needs a registered OAuth application, a client secret and its rate limits.
reddit-voc reads Arctic Shift instead. Its project page describes itself as making Reddit data accessible to researchers, moderators and everyone else, through dumps, an API and a web tool, and it answers from hosts that Reddit blocks. Its API is free and described as limited, so the tool spaces requests and backs off. That is the easy part. There are 3 traps in the analysis, and a tool that ignores them gives you a confident wrong answer.
Trap 1: noise that looks like sentiment
A good share of what an unfiltered pull returns was never a human opinion. AutoModerator posts removal notices, bots remind and repost, and removed comments survive in archives as literal strings. On October 31, 2026 I pulled the top 40 threads of r/SEO for the previous 30 days and counted what the tool throws away:
| r/SEO, top 40 threads, October 1 to 31, 2026 | Comments | Share |
|---|---|---|
| Raw comments | 1,918 | 100% |
| From AutoModerator | 296 | 15.4% |
| All filtered as bots or deleted authors (includes AutoModerator) | 592 | 30.9% |
| Kept for analysis | 1,326 | 69.1% |
Measured with reddit-voc against Arctic Shift. One subreddit, one month. The share will differ by community.
Count those and your sentiment is partly a measure of moderation policy. So the tool strips known bot authors, recognized bot phrasing and dead bodies before anything is scored, and you cannot turn that off.
Trap 2: a baseline that flatters every brand
Say you want to know what a brand is distinctively criticized for. The naive approach measures how often that brand appears next to words such as broke, overpriced or refund, against the rate across the whole subreddit. The problem: documents that mention any brand tend to be longer than the average post, so every brand scores above average, and the comparison says nothing.
The honest denominator is the pool of brand-mentioning documents. reddit-voc compares each brand's complaint rate with the pooled set of all brand-mentioning documents, and reports an index where 100 means the same as its peers and anything above about 130 is a distinctive weakness. This is the output on the synthetic sample that ships with the tool, trimmed and with punctuation simplified:
$ python3 reddit_voc.py --fixture fixtures/sample-corpus.json \
    --brands "Acme Audio,Zenith,Northwind,Kestrel" --min-docs 20

Voice of Customer  r/SyntheticGear
  150 posts, 289 comments, 2026-01-01 to 2026-06-28
  sentiment  51% positive, 7% negative, ratio 7.26

  Share of voice
    Acme Audio      51   27.3%  ##################
    Northwind       48   25.7%  #################
    Kestrel         44   23.5%  ################
    Zenith          44   23.5%  ################

  Complaint fingerprint  (100 = same as peer brands; >130 distinctive)
    baseline: 150 brand-mentioning documents
    Zenith      n=44   19 pos / 5 neg   sharpest: customer service 320
        customer service      320
        returns & refunds     146
    Northwind   n=48   13 pos / 7 neg   sharpest: defective on arrival 278
        defective on arrival  278
        quality / durability  238
    Kestrel     n=44   22 pos / 0 neg   sharpest: setup / installation 256
        setup / installation  256
        comparison shopping   170
    Acme Audio  n=51   28 pos / 5 neg   sharpest: delivery & shipping 233
        delivery & shipping   233
        price / value         224
Trap 3: a brand's own community is not neutral ground
I would expect a brand's own subreddit to read more positively than the general category subreddit. That is not a scandal. Enthusiasts self-select, staff post announcements, and unhappy buyers take complaints where they will be believed. The useful question is by how much, because if the gap is wide, a shopper who cross-checks the neutral subreddit finds a different story.
reddit-voc measures this venue gap: the positive-to-negative ratio inside a brand's own subreddit divided by the same ratio for that brand's mentions on a neutral subreddit you name. Then it argues with its own result. The exact multiple depends on arbitrary choices, such as whether the ratio is smoothed and whether you filter the brand's side to posts naming the brand. So it re-runs the gap under each combination, 4 variants, and reports the range. If the variants disagree, it says so and tells you to compare brands by rank.
What it measures
| Output | The question it answers |
|---|---|
| Share of voice | Who owns the conversation in this category, and where do you rank? |
| Complaint fingerprint | What is each brand distinctively criticized for, against its direct peers? |
| Venue gap | Is a brand's own community representative, or effectively marketing? |
| Most-asked questions | What decisions is the market trying to make? |
Recurring themes (--themes) | What exact phrases do customers use? |
Verbatims (--verbatims) | Which real comments sit behind a fingerprint, so you can read them yourself? |
How to use it
It is one Python file with no dependencies. Clone the repository or download reddit_voc.py on its own and run it with Python 3.8 or newer.
# what a whole community talks about
python3 reddit_voc.py SEO --days 30

# narrow to a topic with full-text search
python3 reddit_voc.py SEO --days 90 --query "core update"

# brand share of voice plus complaint fingerprints
python3 reddit_voc.py headphones --brands "sony,bose,sennheiser,anker"

# the real comments behind a fingerprint
python3 reddit_voc.py headphones --brands "sony,bose" --verbatims --quotes 3

# compare a brand's own community with neutral ground
python3 reddit_voc.py acmeaudio --brand acme --vs headphones
The archive is free and its API is limited, so the polite pattern is to pull once and analyze many times:
python3 reddit_voc.py headphones --days 180 --save headphones.json
python3 reddit_voc.py --fixture headphones.json --brands "sony,bose"
The default complaint axes are generic: price, quality, defects on arrival, customer service, returns, warranty, delivery, setup, sizing and comparison shopping. Swap them for your category with a small JSON file passed to --issues. To check the internals yourself, --selftest runs 20 checks over the matching, baselining and smoothing logic, all of which passed when I ran it on October 31, 2026.
From raw threads to a content plan
Numbers only help if they change what you do next. Suppose you run it on a category subreddit for a headphone brand and read the blocks in order.
- Share of voice shows where the brand stands in the conversation, not where its ad budget says it stands, and which competitors are worth a closer look.
- The complaint fingerprint is where the strategy lives. Because it is peer-based, 233 on delivery does not mean people mention delivery. It means this brand attracts delivery complaints at more than twice the rate of its rivals. That is a flag for operations and a page worth writing, and read across competitors it is a map of where to differentiate.
- Most-asked questions are sorted by reply count, which shows how hard a question pulls the community. A thread on which model suits a commuter who takes calls gives you the format, the use case and the intent.
- Recurring themes hand you the vocabulary for headings and for the first lines of a page.
5 ways search teams can use it
- Competitive read before a meeting. Know what a category's customers complain about, and what competitors get away with.
- A check on what AI may repeat. If a brand reads far better on its own subreddit than on neutral ground, the venue gap shows the exposure. Whether an engine will weigh it is unmeasured.
- Content briefs. The ranked question list is an editorial calendar written in your buyers' words.
- Product and support feedback. The fingerprint is a defensible thing to hand over: what the market criticizes, relative to rivals.
- Launch monitoring. Saved corpora are dated snapshots, so pull monthly and compare.
Reading the output honestly
- Sentiment is lexical. It matches positive and negative marker phrases. That is good enough to compare and not good enough to say that 49% of customers are happy.
- The ratio is smoothed. 22 positives and 0 negatives is not a ratio of 22, so the math adds 1 to each side.
- Thin brands are held back. A brand with fewer mentions than
--min-docs, 100 by default, is listed as skipped. If every brand falls short, the whole fingerprint block is left out, so a missing block means too little data and not an absence of complaints. - Removed content is invisible. Moderation deletes complaints along with spam, so every rate is a rate among surviving posts.
- Check the subreddit is what you think it is. Names collide: r/Corona is a city in California, and r/Java is a programming language.
Where it fits
reddit-voc is part of the SEO Pro Check line of free, open-source command-line tools. On the AI search side it sits next to ai-crawler-audit, which shows which AI bots a site allows, and llms-txt-kit, which builds an llms.txt file. For the wider picture of what crawlers can reach, see my study of 400 sites, and for how to measure the result, monitoring AI search visibility.
FAQ
Do I need a Reddit API key or developer account?
No. reddit-voc reads the Arctic Shift public archive and not Reddit's own API, so there is no application to register, no client secret and no OAuth flow. Download the file and run it.
Does it scrape reddit.com?
It does not touch reddit.com at all. It reads a free public archive, spaces its requests, and backs off when asked to. Pull once, save the corpus and analyze locally. Whether that data fits your own use is your call.
Can it analyze a topic instead of specific brands?
Yes. Leave out --brands and you still get overall sentiment, the ranked questions and, with --themes, recurring phrases for the whole subreddit.
How accurate is the sentiment scoring?
It is lexical: good enough to compare brands or venues, not a substitute for a trained classifier on absolute numbers. It cannot read sarcasm or negation. Use it to rank, not to score.
Is it finished software?
No. The README marks it as beta: it runs end to end and passes its self-test, but flags and output formats may change.
Why does the fingerprint not show up on my run?
Brands with fewer mentions than --min-docs, 100 by default, are skipped, and if all of them fall short the block is left out entirely. On a small sample, lower it, as I do with --min-docs 20 on the sample corpus, and treat those thin results with care.
reddit-voc is built and maintained by SEO Pro Check. It is not affiliated with, endorsed by or connected to Reddit, Inc. Reddit and subreddit names are trademarks of their owners, and brand names in the sample output are fictional.
Sources I read
- reddit-voc on GitHub. MIT license, beta. Read and run October 31, 2026.
- Arctic Shift project page
- Minuttia and Convex Works: Self-Promotional Content Data Study. August 2026. My source for the Reddit citation figures.
Take this with you
The assistant links open with a question about this page already written.
Claude Vincent is a technical SEO consultant focused on crawlability, rendering, and AI-search visibility. He writes the field guides and case studies at SEO ProCheck, with a bias toward the durable, unglamorous work that decides whether search engines and AI answer engines can actually read and cite a site.
About SEO ProCheck
Technical SEO consulting and GEO strategy with 20 years of enterprise experience. Case studies, resources, and tools for search and AI visibility.
Subscribe to our newsletter!
Recent Posts
- What's Actually Happening With AI Search, and What You Can Honestly Measure November 16, 2026
- Reddit Voice-of-Customer Analysis, Free and Without an API Key November 14, 2026
- Locked Out of Search Console? Verify Again With a New Account November 12, 2026