
TL;DR
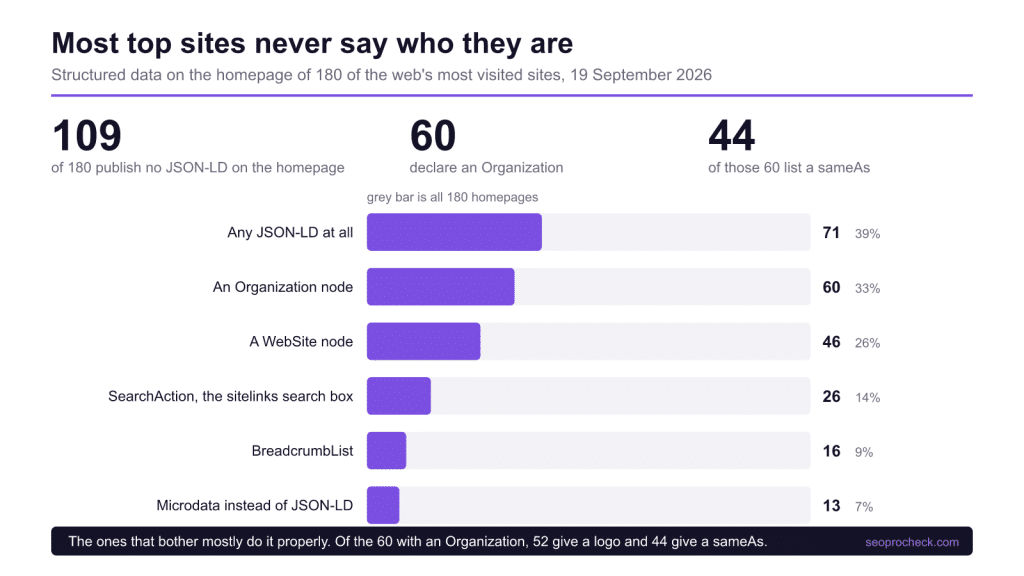
Entity SEO advice usually assumes everyone is already doing the basics and the game is refinement. I read the homepage of 180 of the most visited sites on the web to see who actually publishes structured data about themselves. Most do not publish any.
- 109 of 180 (60.6%) have no JSON-LD on the homepage at all.
- 60 (33.3%) declare an Organization, 46 a WebSite node, 26 a SearchAction, 16 a BreadcrumbList.
- The ones that bother mostly do it properly: of those 60, 57 give a name, 52 a logo and 44 at least one
sameAs. - Microdata is effectively finished as a homepage format: 13 of 180.
- This is a floor, not a ceiling. It says the basic work is still unclaimed, not that structured data is optional.
Why measure this at all
Entity coverage gets written about as an advanced topic. Disambiguation, knowledge panels, sameAs graphs, the shape of an organisation across the web. All of that assumes the first step is done, which is a site saying in machine readable terms who it is.
So rather than start at the interesting end, I started at the boring one. One request per homepage, parse every JSON-LD block, and record what is actually declared.
What came back
| On the homepage | Sites | Share | What it is for |
|---|---|---|---|
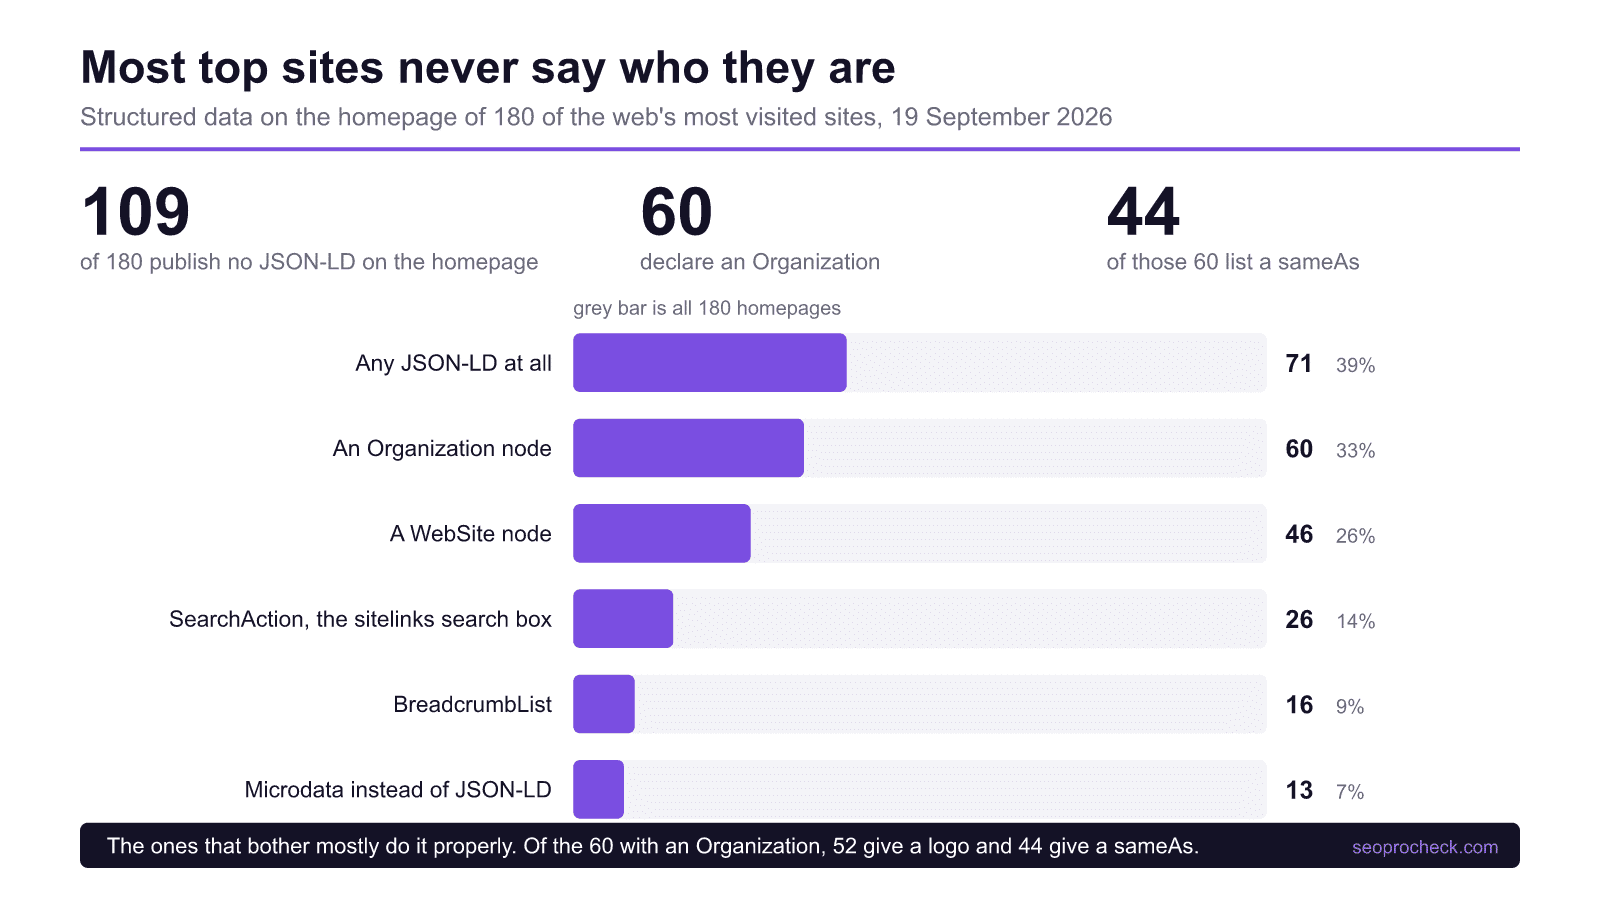
| Any JSON-LD | 71 of 180 | 39.4% | The container for everything below |
| Organization | 60 of 180 | 33.3% | Says which company this site belongs to |
| WebSite | 46 of 180 | 25.6% | Names the site as a thing, separate from the company |
| SearchAction | 26 of 180 | 14.4% | The sitelinks search box in a result |
| BreadcrumbList | 16 of 180 | 8.9% | The path shown under a result instead of a raw URL |
| Microdata | 13 of 180 | 7.2% | The older inline format, now rare |
The first row is the one worth sitting with. 109 of these sites publish nothing at all in the format search engines and assistants read most easily, on the single page most likely to be crawled and cited. These are not small sites.
The half that does it does it well
The second finding softens the first. Among the 60 sites that declare an Organization, the work is not token: 57 give a name, 52 a logo, 44 at least one sameAs, and the median sameAs list is 6 entries with one site listing 32.
So this is not a story about everyone doing it badly. It is a split. A site either treats structured data as part of how it publishes, and then does it properly, or it does not do it at all. Very few sit in between with a broken half-attempt.
That matters for where to spend your effort. If you have nothing, the first hour is worth more than anything else on this page: a name, a URL, a logo, and the handful of profiles that are unambiguously you.
What to publish, in order
One, an Organization node with name, url and logo. That is the machine readable version of who owns this site, and it is the anchor everything else references.
Two, sameAs pointing at profiles you control. The point of sameAs is disambiguation, so list the accounts that are unambiguously the same entity and skip the ones that merely mention you. Six is a normal number. Thirty two is not better.
Three, a WebSite node. The site and the company are different things and conflating them is the most common modelling mistake. Add SearchAction only if your site search actually works from a query string.
Four, breadcrumbs on deep pages. Nine percent of top homepages carry a BreadcrumbList, which is low, and on a homepage it is arguably unnecessary. On a category or article page it is what replaces the raw URL in a result.
Then check the thing that decides whether any of it is read: whether a crawler can fetch the page at all. In the access study a fifth of these same sites did not serve GPTBot real content, and markup on a page nothing can reach is a note to nobody. The current crawler names to check against are in the user agent reference.
What this does not say
It does not say these sites are hard to understand. A company with a large brand footprint is resolved from many signals, and the biggest names here are understood with or without markup. Structured data is a shortcut, not the only route.
It also measures the homepage only, in one pass, from one location. A site can carry rich markup on product or article templates and nothing on the homepage, which for a retailer is a defensible choice. Read this as the state of the front door, not of the whole house.
Questions people ask about this
Is structured data a ranking factor?
Not directly, and Google says so. It earns eligibility for features such as breadcrumbs, sitelinks search and rich results, and it makes an entity easier to resolve. Treat it as a way to be understood and displayed, not as a lever on position.
If 109 of the biggest sites skip it, can I skip it?
Their brands are resolved from a large footprint that most sites do not have. The less known your name, the more the explicit version is worth. The finding is that the basic work is unclaimed, not that it is pointless.
How many sameAs entries should I list?
Among the sites measured here the median is 6. List the profiles that are unambiguously the same entity and that you control. A long list padded with directory pages adds noise, not confidence.
Should I use microdata or JSON-LD?
JSON-LD. Only 13 of 180 homepages still use microdata, Google recommends JSON-LD, and keeping markup out of the visible HTML means changing the page design cannot silently break it.
Does the homepage need a BreadcrumbList?
Usually not, since it is the root. Breadcrumbs earn their place on category and article pages, where they replace the raw URL in a result with a readable path.
How do I check what my own site emits?
Open the page source and search for application/ld+json, or paste the URL into Google's Rich Results Test. Check the rendered page as well as the source if your markup is injected by JavaScript, since the two can disagree.
Method: one homepage request per host on 19 September 2026 from a single residential connection in the United States, reading up to 700,000 bytes. Every application/ld+json block was parsed and every @type recorded, including nested nodes and @graph members. 180 of the 184 hosts returned a 200. Blocks that failed to parse were counted as absent, so these figures are a floor.
Take this with you
The assistant links open with a question about this page already written. Nothing is sent until you press enter.
Claude Vincent is a technical SEO consultant focused on crawlability, rendering, and AI-search visibility. He writes the field guides and case studies at SEO ProCheck, with a bias toward the durable, unglamorous work that decides whether search engines and AI answer engines can actually read and cite a site.
About SEO ProCheck
Technical SEO consulting and GEO strategy with 20 years of enterprise experience. Case studies, resources, and tools for search and AI visibility.
Work With Me
Technical SEO audits, GEO strategy, site migrations, and international SEO. Hourly consulting for teams who need hands-on support, not just reports.
Subscribe to our newsletter!
Recent Posts
- Most Top Sites Never Say Who They Are in Structured Data October 14, 2026
- Homepage Titles Are Mostly Too Short, Not Too Long October 8, 2026
- Who Actually Serves an llms.txt? 184 Top Sites Measured September 29, 2026